AI Is Entering Defense Workflows. Now the Pentagon Needs a Way to Evaluate It.
Last updated 06:25 AM EDT • Read time: 5m
When I ran joint operations centers at U.S. European Command and U.S. Army Pacific, new officers regularly rotated onto the watch floor to brief senior leaders.
I would never allow a new officer to brief a four-star commander without first watching them work. I need to know how clear they speak, how well they understand the material, and how they respond when challenged. Trust must be built.
Artificial intelligence deserves the same treatment.
AI tools are rapidly entering Defense Department workflows through initiatives such as GenAI.mil and other experimentation programs. The debate is no longer whether AI can generate useful outputs. The question is whether the department can trust, understand, and control how those systems behave in real operational environments.
Many organizations are approaching AI like traditional software: install the tool, connect it to data, and use the output. But AI systems are different. They are probabilistic systems that interpret data, make inferences, and generate conclusions with varying levels of confidence.
The critical task is not simply running AI models. It is observing how they work.
Watching AI Work
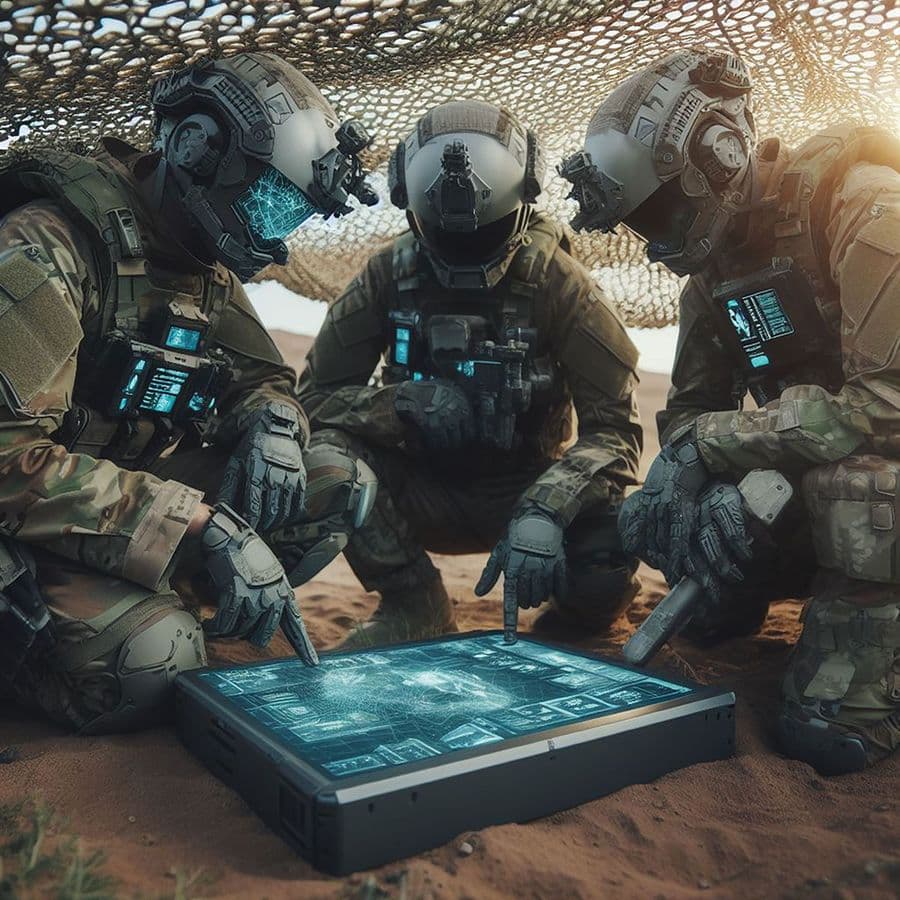
A secure visual workbench allows teams to observe how AI systems process information step by step. Instead of treating the model as a black box that produces a final answer, analysts can see intermediate outputs, compare results from multiple models, and examine how different data inputs affect the outcome.
This matters because AI models frequently produce different answers to the same question.
Ask multiple models to analyze satellite imagery of an airfield, for example, and one may correctly identify aircraft, while another may mislabel civilian platforms as military assets. Ask them to interpret operational reports, and they may draw very different conclusions about what matters most.
Without the ability to compare outputs side by side, those differences and those potential errors can remain hidden. A visual workbench creates an environment where analysts can run multiple AI tools on the same dataset and examine how their conclusions diverge or converge. Over time, that process helps teams understand which systems perform best under specific conditions. In other words, it allows operators to build trust.
The Risk of Blind Adoption
The Defense Department faces pressure to move quickly with AI. Competitors are investing heavily, and policymakers want to accelerate experimentation and deployment.
But speed creates risk.
AI systems are persuasive. Their outputs often read with the confidence and clarity of a human analyst—even when the underlying reasoning is flawed, or the data is incomplete.
In one experiment I conducted, the same AI system reviewed a set of documents related to a fictional case. When a small but important piece of information was missing, the model generated a compelling conclusion that was entirely wrong. When that missing detail was added, the system produced a completely different—and correct—analysis.
The difference between those two outcomes was not obvious in the final text. Only by examining the process and comparing multiple runs could the problem be identified.
If analysts rely on a single AI output without visibility into how it was generated, they risk accepting conclusions that appear authoritative but rest on fragile assumptions.
Why Security Matters
Evaluating AI systems also requires a controlled environment.
Defense organizations cannot freely upload operational data into public AI tools to test their behavior. Sensitive datasets, mission plans, and intelligence products must remain protected—even during experimentation.
A secure visual workbench provides a place where teams can safely test models using operationally relevant data. Analysts can run multiple AI systems against the same information, observe how they perform, and refine workflows without exposing sensitive material.
Access can also be tightly controlled. Only the teams responsible for evaluation see the results, allowing experimentation without broadcasting early failures or flawed outputs.
This matters because testing AI often means discovering where models break down.
Addressing the Skeptics
Some critics argue that adding another layer of oversight will slow AI adoption. If the goal is speed, they ask, why introduce additional evaluation steps?
The answer is that unchecked speed can lead to costly mistakes.
Operational systems that rely on AI must be trusted by the humans who use them. If analysts repeatedly encounter outputs that are inconsistent or poorly understood, they will quickly stop relying on the tool. Careful evaluation ultimately accelerates adoption by building confidence.
Others argue that model benchmarking and formal testing already exist. That is true, but many evaluations occur in controlled environments far removed from operational workflows.
What matters is not just whether a model performs well in isolation, but how it behaves when integrated with real data, real users, and real mission systems.
AI evaluation also cannot be treated as a one-time certification. Foundational models evolve. Data changes. Operational conditions change. Foundational models evolve. A system that performs well today may behave differently after an update, when exposed to new inputs, or when combined with other tools in a workflow.
Defense organizations will need the ability to continuously retest these systems as conditions evolve. A secure visual workbench allows teams to revisit workflows, compare results over time, and ensure that trust in AI systems remains justified.
Building Trust Over Time
When a new officer proves their competence, I eventually stop watching every step they take. Trust grows through repeated performance.
The same will happen with AI.
At first, analysts may examine each stage of an AI workflow, reviewing intermediate outputs and comparing results across models. As confidence increases, they may rely more heavily on automated outputs.
But that trust should be earned through observation—not assumed.
Artificial intelligence is already moving from research projects into everyday defense workflows. The real challenge is ensuring that the people who depend on these systems understand how they behave and when they can be trusted.
Building that confidence will require more than new models. It will require environments where those models can be observed, compared, and tested before they influence real decisions.
COL Jim Allen (U.S. Army, ret.) is Bluescape’s Lead Account Executive for INDOPACOM and a retired U.S. Army Colonel, with 30 years of service as an infantry officer. He served as Chief of Operations for U.S. European Command and U.S. Army Pacific, and brings more than a decade of experience in military operations centers spanning brigade, division, component command, and combatant command levels.
In Pursuit of Nuclear Abolition
By Peter Huessy • RealClearDefense
Innovation Alone Won’t Prepare the U.S. for the Future Battlefield
By Joshua Segal • RealClearDefense
The sUAS Tactical Trifecta
By Bryan T. Woody • RealClearDefense
The Revolutionary War: When Strategic Options Share the Same Weakness
By Henry Yep • RealClearDefense
The Houthis Are Testing the Limits of Collective Defense
By Saima Afzal • RealClearDefense
Who Shoots Down the Drone Over the Shipyard?
By John Ferrari & Dillon Prochnicki • RealClearDefense
Northrop Grumman Breaks Out the Big Guns at AUSA
By Daniel Terrill, Defense News
Army Pursuing Diverse Array of New Anti-Air Interceptors
By Trevithick, The WarZoneWho Shoots Down the Drone Over the Shipyard?
By John Ferrari & Dillon Prochnicki, RCD
F-35C Lands for the First Time on a Ford-Class Aircraft Carrier
By The Aviationist